I have a confession: my Twitter favourites are a disaster.
Hundreds of saved articles. Papers I was going to read. Threads I bookmarked at 11pm telling myself “tomorrow”. Tutorials I saved three times because I forgot I already had them.
The problem isn’t finding interesting content — there’s too much of it. The problem is that saving something and actually reading it are two completely different behaviours. The bookmark is a lie I tell myself.
So instead of trying to fix my habits, I built a bot to deal with the mess.
What tl-dr-bot actually does
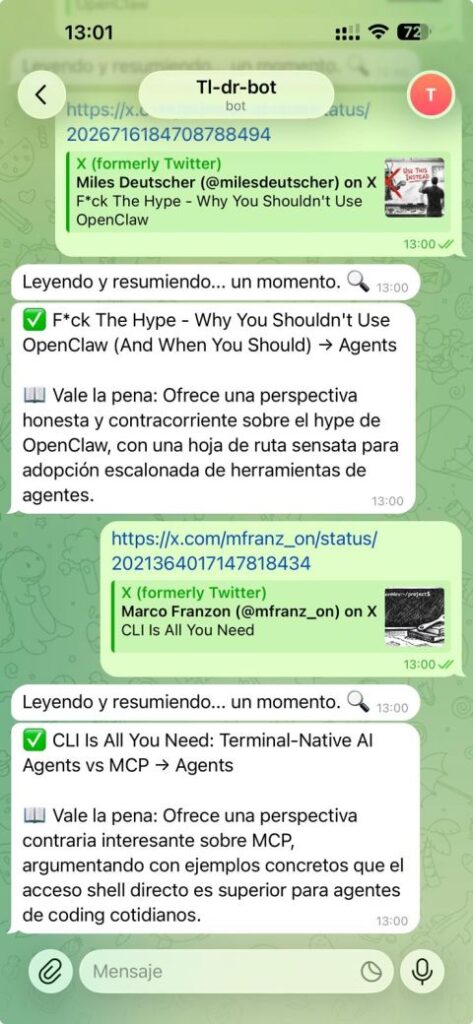
The idea is simple: you send a URL to a Telegram bot, and it does three things.
First, it reads the article. Not you — the bot. It fetches the full content, even on pages that are heavy on JavaScript or behind a basic paywall.
Second, it decides whether it’s worth your time. This is the part most tools skip. It doesn’t just summarize everything — it makes a judgment call. Is this actual signal, or is it hype? If the answer is “hype”, the article goes to a trash folder. Automatically. You never see it again.
Third, if it’s worth reading, it writes a structured summary — three key points, a category, related concepts — and saves it directly to my Obsidian vault on GitHub. No copy-paste. No manual filing.
The result: I send URLs whenever I find something interesting, and my knowledge base grows on its own.
Why this is an agent and not just a chatbot
I’ve been thinking about this a lot because the word “agent” gets thrown around loosely.
A chatbot answers your question. An agent takes an action based on a goal.
tl-dr-bot doesn’t wait for me to tell it what to do with each article. It has a set of criteria, makes a decision, and executes a chain of steps: fetch → evaluate → summarize → classify → save (or discard). I just trigger it with a URL.
That decision step is what makes it an agent. It’s not routing my request to a template — it’s applying judgment. And that judgment is handled by Claude, Anthropic’s model, which reads the content and returns structured data: title, bullets, category, and a yes/no on whether it’s worth keeping.
Product people often ask me: “so what’s the actual value of using an LLM here instead of just a scraper?” The answer is that the evaluation step is genuinely hard to rule-encode. What counts as “worth reading” depends on context, recency, relevance to what I’m working on. A rules engine would need hundreds of conditions. Claude does it in one prompt.
The technical stack (simplified)
- Telegram: the interface. You send a URL, it responds.
- Jina AI Reader: fetches the actual article content, including JS-heavy pages.
- Claude API: reads the content, evaluates it, and returns a structured summary.
- GitHub API: saves the resulting markdown file to my Obsidian vault, which syncs to my phone.
The whole thing runs on a small server (€6/month on Hetzner) and restarts automatically if it crashes. I built it in a few hours with Claude Code.
What surprised me
The discard function is more useful than the summary. I thought the value was in the summaries. But it turns out the bigger relief is knowing that the bot filtered out something that wasn’t worth my time. I don’t have the nagging feeling that I’m missing something — because something made the call for me.
The categories emerge naturally. I defined a list upfront: Agents, MCP, LLMs, Tools, Career, Tutorials, Trash. But Claude interprets them sensibly even for edge cases. It doesn’t hallucinate new categories — it finds the best fit.
It changes how I save things. Before, I’d save articles selectively because I knew I’d have to process them manually. Now I save more aggressively, because the cost of sending a bad URL is zero — it just goes to trash.
Why product people should care
If you’re building products with AI, tl-dr-bot illustrates a design principle worth internalising: the most valuable thing an AI agent can do is make a decision so you don’t have to.
Summarisation is useful. But judgment is where the leverage is.
Most AI features I see in products are in the summarisation category: take this input, format it nicely, show it to the user. That’s fine. But the higher-value pattern is: take this input, evaluate it against a goal, and act — without asking the user to confirm every step.
The tricky part is that users need to trust that the agent’s judgment is good enough. With tl-dr-bot, I calibrated the prompt over a few iterations until the trash/keep split felt right. That calibration work is the actual product design challenge, not the code.
Try it yourself
tl-dr-bot is open source: https://github.com/sidddi/tl-dr-bot
The README has setup instructions. You’ll need a Telegram bot token, an Anthropic API key, and an Obsidian vault on GitHub. If you get stuck or want to discuss the agent design, I’m on LinkedIn.